
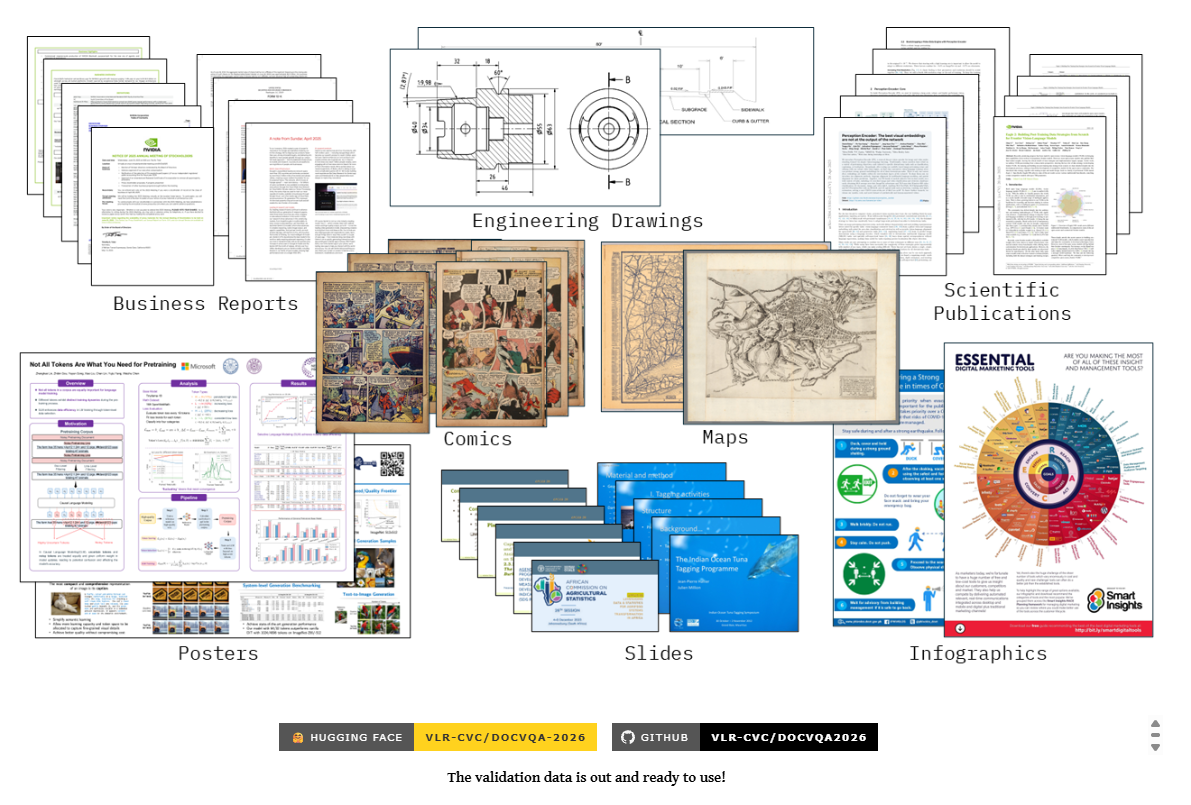
screenshot taken from: https://www.docvqa.org/challenges/2026
When
Wednesday, 11th November 2026, 6:00pm to 8:45pm
Where
Zalando Office, Hedwig-Wachenheim-Strasse 7, Berlin, Germany
Hosting Organization
Elastic Berlin User Group
Participation Fee
Free Entrance
Agenda
Socializing, Host Intro, Talk 1, Pizza Break, Talk 2, Socializing
Topics Covered
Snack Paper Bags (Host Intro), Comparing Supervision Signals for Visual Document Retrieval (Talk 1), Leveraging Visual Search for AI-Powered Product Discovery (Talk 2)
I’ve learned something today
- The Cumulative Latency Tax arises when multiple sequential LLM inferences compound response times. Even small delays accumulate in customer-facing commerce applications. This degrades the shopping experience and negatively impacts customer engagement and conversion rates. Engineers must carefully balance the benefits of additional inferences against their latency costs.
- Intent inference helps identify a customer’s underlying goals throughout the shopping journey by interpreting behavioral signals, search queries, and interactions. Since customer intent evolves across touchpoints, engineers must continuously refine these predictions to deliver relevant experiences.
- The GitHub repository github.com/elastic/vdr-teacher-signals is a public research repository from Elastic exploring how vision-language models can improve visual document retrieval. It compares four supervision signals: teacher-judged hard negatives, score distillation, attention grounding, and description alignment.
- Amazon Rekognition is an AWS computer vision service that uses machine learning to analyze images and detect potentially unsafe content, including nudity, violence, and other inappropriate material. It can be integrated into an AWS Lambda function to automatically scan user-uploaded images and flag or block unsafe content before it appears on your website.
- A packshot is a clear, high-quality image of a product, typically shown against a plain background. It is better suited for visual search because, unlike a busy picture, it allows algorithms to identify and match the product more accurately.
- Using CLIP, a model that maps images and text into a shared embedding space, image and text embeddings can be combined through a weighted average (0.4 × text + 0.6 × image). This balances semantic and visual information to improve retrieval accuracy.
- The venue offers a direct view of the East Side Mall and its buzzing urban atmosphere:
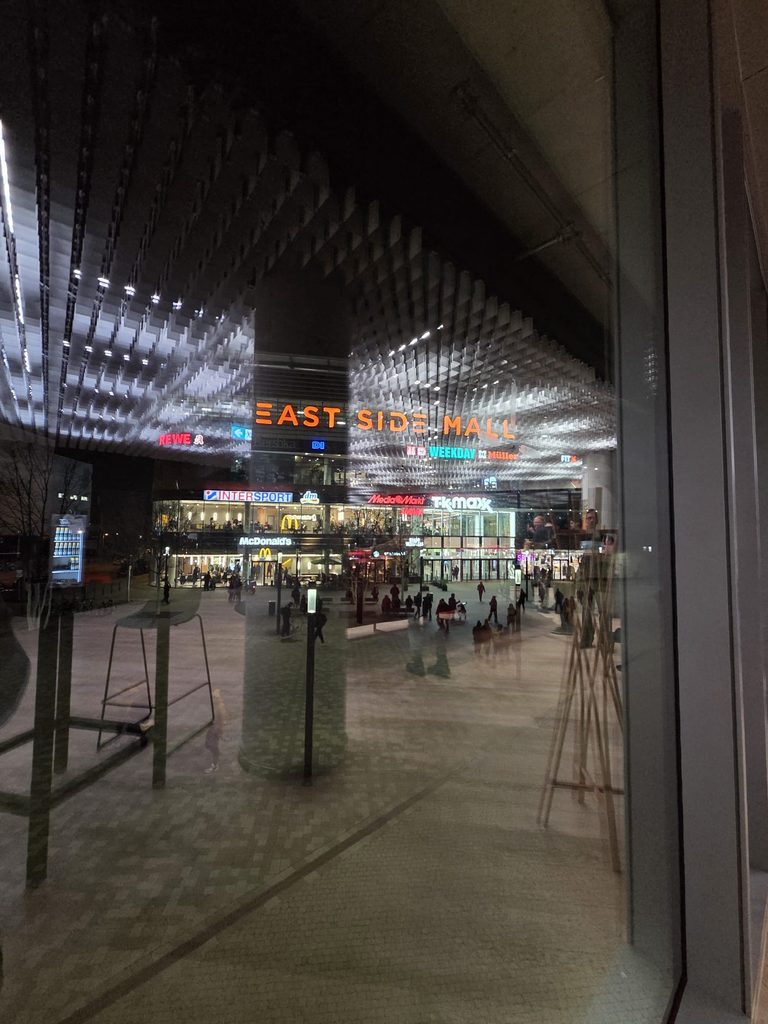
picture taken at venue
Published:
Modified: